Add vendor-agnostic wgpu compute backend - #44
naitikpahwa18 wants to merge 20 commits into
Conversation


Signed-off-by: Naitik Pahwa <naitikpahwa11@gmail.com>

for more information, see https://pre-commit.ci
There was a problem hiding this comment.
Pull request overview
This PR replaces the CUDA-dependent multibeam sonar compute pipeline with a modular backend architecture. A WGPU-based GPU backend (using Rust + WGSL shaders) and a CPU reference backend are introduced, selectable at runtime via the DAVE_SONAR_COMPUTE_BACKEND environment variable. The sonar sensor is refactored to use a ComputeBackend interface, and computation is moved to a background thread to avoid blocking the rendering pipeline.
Changes:
- New
ComputeBackendabstraction with WGPU (GPU via WGSL shaders + Rust FFI) and CPU implementations, replacing direct CUDA kernel calls - Background compute thread in
MultibeamSonarSensorwith snapshot-based decoupling from the render thread, plus consistent timestamping for ROS messages - Build system migrated from CUDA to a Rust-based
wgpu_vendorpackage with CMake integration, and runtime backend selection via launch arguments
Reviewed changes
Copilot reviewed 26 out of 27 changed files in this pull request and generated 9 comments.
Show a summary per file
| File | Description |
|---|---|
multibeam_sonar/sonar_compute_backend.hh |
New abstract backend interface and data structures |
multibeam_sonar/sonar_compute_cpu.cc |
CPU backend implementation and backend factory |
multibeam_sonar/sonar_compute_wgpu.cc/hh |
WGPU backend: C++ wrapper calling Rust FFI with CPU fallback |
multibeam_sonar/MultibeamSonarSensor.cc/hh |
Background compute thread, snapshot-based pipeline, backend integration |
multibeam_sonar/CMakeLists.txt |
Removed CUDA, added wgpu_vendor dependency |
wgpu_vendor/sonar_wgpu_rust/src/lib.rs |
Rust FFI entry point: GPU dispatch, staging readback, CPU FFT fallback |
wgpu_vendor/sonar_wgpu_rust/src/pipeline.rs |
GPU context singleton: device init, buffer management, pipeline compilation |
wgpu_vendor/sonar_wgpu_rust/src/fft.rs |
CPU FFT (Cooley-Tukey + Bluestein) |
wgpu_vendor/sonar_wgpu_rust/src/shaders/*.wgsl |
WGSL compute shaders: backscatter, convert, matmul, FFT |
wgpu_vendor/CMakeLists.txt |
Rust cargo build integration with CMake |
multibeam_sonar_system/CMakeLists.txt |
Simplified: removed CUDA conditionals |
multibeam_sonar_demo/launch/multibeam_sonar_demo.launch.py |
Added compute_backend launch argument |
multibeam_sonar_demo/scripts/plotdata.py |
Save to file instead of plt.show() |
dave_interfaces/CMakeLists.txt |
Removed gz-cmake3/gz-msgs10 dependencies |
models/.../model.sdf |
Debug comment for non-power-of-2 FFT testing |
💡 Add Copilot custom instructions for smarter, more guided reviews. Learn how to get started.

Signed-off-by: Naitik Pahwa <naitikpahwa11@gmail.com>
for more information, see https://pre-commit.ci

Signed-off-by: Naitik Pahwa <naitikpahwa11@gmail.com>


|
@naitikpahwa18 Could you provide quick how-to test document? |
Signed-off-by: Naitik Pahwa <naitikpahwa11@gmail.com>

|
Hi @woensug-choi, I've added a quick demo guide in the latest commit. Please let me know if anything else needs to be added. |

|
@naitikpahwa18 Thank you for the quick response! I will give it a spin sometime next week on MacOS |
|
@naitikpahwa18 I've tested on MacOSX with some changes. Note at https://github.com/naitikpahwa18/dave/blob/wgpu_integration/gazebo/DEMO_GUIDE_AppleSilicon_MacOSX.md. Dave currently assumes ROS2 Jazzy and Gazebo Harmonic.
|

|
Thanks for testing on MacOSX and updating the docs! (I'm on ROS2 Rolling + Gazebo Jetty on my end) |

a1107b7 to
b15574d
Compare
Signed-off-by: Naitik Pahwa <naitikpahwa11@gmail.com>
|
@woensug-choi I have tested the current wgpu implementation with |
|
@naitikpahwa18 Apologies for the delayed response. Although I'm aware of the late ping-pong, I would be delighted to see this agnostic sonar plugin upstreamed. Lack of rays is especially visible when grazing the seabed (e.g. 4. Local Search Scenario at Wiki Doc showing stripe pattern). What do you mean by slightly more distorted? |
|
Agreed, increasing rays from 300 to 9000 significantly reduces the stripe pattern, consistent with what you described. Please ignore the "slightly more distorted" comment, I was misinterpreting the RViz visualization at the time. 
|

Signed-off-by: Yeseol Gwon <172019512+yeseorizi@users.noreply.github.com>
Signed-off-by: Yeseol Gwon <172019512+yeseorizi@users.noreply.github.com>

|
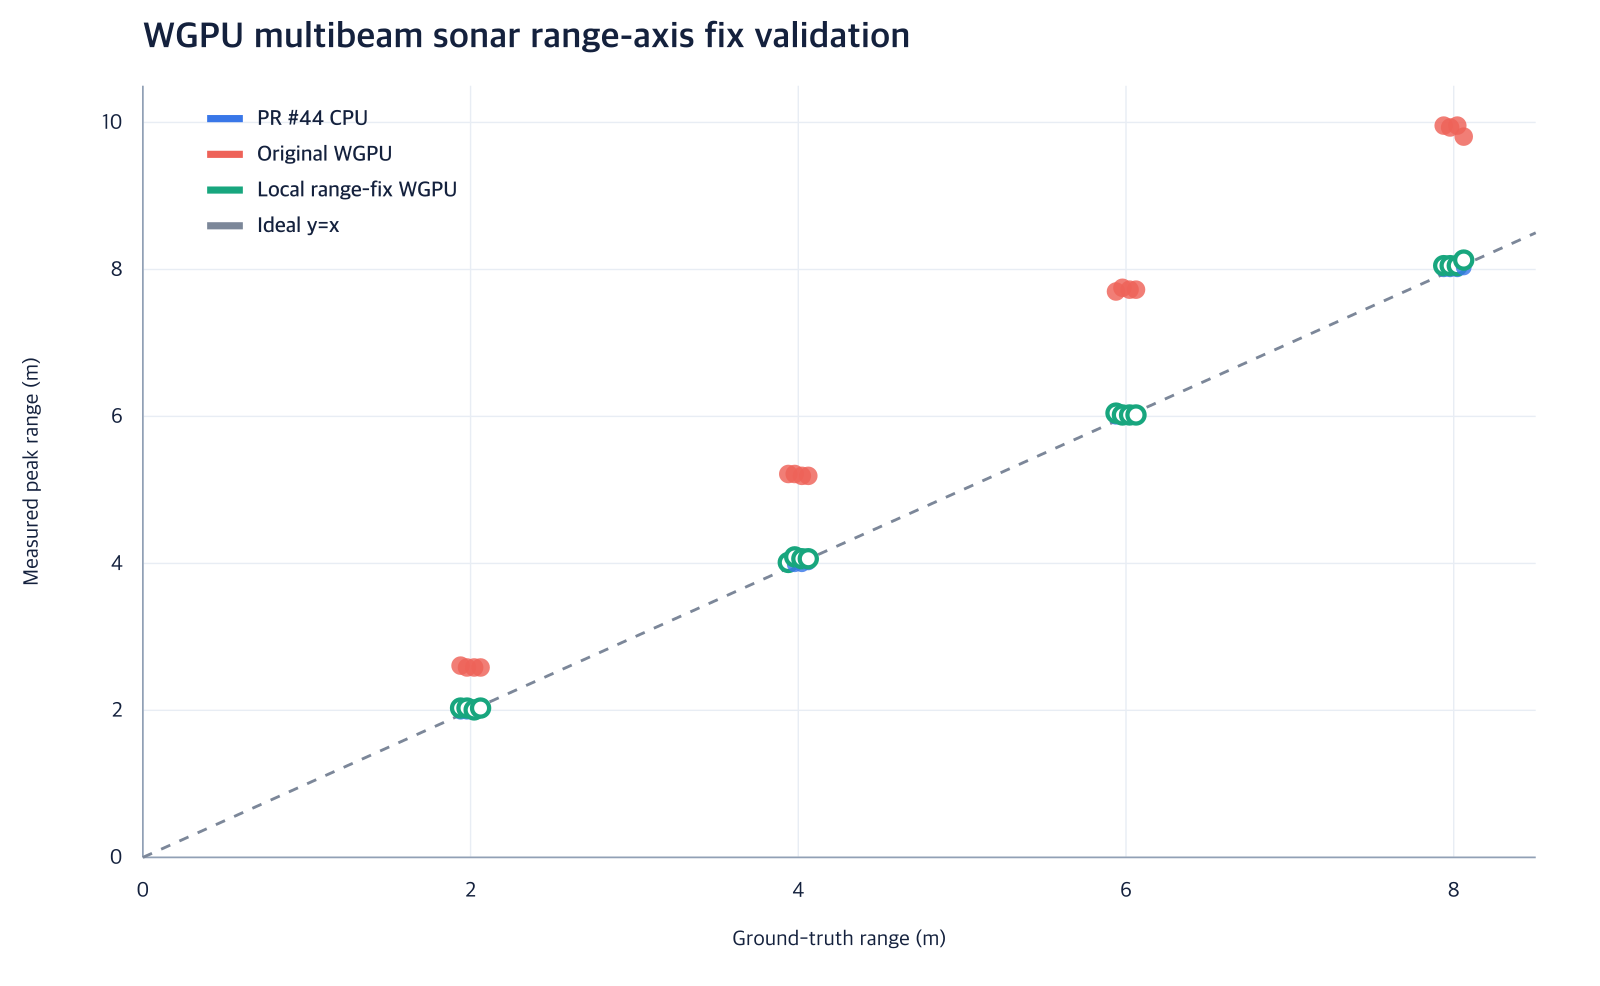
Hi @naitikpahwa18, I validated the WGPU multibeam-sonar backend on Apple M2 / Metal and found a possible range-axis mismatch in the non-power-of-two FFT path. I pushed two separate signed-off commits for review:
Why I changed itFor the default Candidate changeThe candidate keeps the 512-point FFT, but during writeback samples the complex padded spectrum at Controlled validation
This is a 96.28% RMSE reduction relative to the original WGPU writeback in the 16-condition matrix.
Full evidence: WGPU padded-FFT range-axis validation I also checked NVIDIA CUDA equivalence has not been tested yet, so I am not claiming complete backend equivalence. Could you please review whether this range-axis interpretation matches the intended FFT/writeback design? I would also appreciate your opinion on the 511 -> 512 edge case and any CUDA comparison you think should be run before merging. We are considering preparing a paper from this numerical analysis and validation. I plan to lead the remaining experiments, analysis, and initial draft; once the technical direction is agreed, I would like to discuss separately how you would like to contribute. |
|
Hi @yeseorizi, I reproduced your matrix on NVIDIA (RTX 4060, Gazebo Jetty): same panel setup, 2/4/6/8 m x 0/15/30/45 deg, 5 frames, peak from the median profile, PointCloud for placement. 1. Range-axis interpretation: confirmed. CUDA runs an exact 2. CUDA equivalence:
Candidate matches CUDA to 0.0022 m RMSE, so I'd consider NVIDIA equivalence covered on this matrix. Your Metal numbers reproduce on Vulkan to within a few percent. 3. 511 -> 512: swept six ratios, 4 distances, 0 deg.
At 511 the candidate comes out slightly better here, where yours came out slightly worse. I don't think either result means much: both differences are smaller than one range bin (~0.02 m), so they sit below what the sonar can resolve. Everywhere else the candidate is clearly better, by more as the ratio grows. At ratio 1.0 your formula already reduces to a plain copy ( 4. On the paper: This is something I'd really like to see happen. The cross-platform angle in particular seems worth writing up properly, and with both sets of validation there's a solid base to build on. Worth talking through what it would cover first. Happy to take that to a separate thread or a call whenever suits you. |
|
Hi @naitikpahwa18, Thank you for reproducing the experiment and for the detailed comparison. Your NVIDIA results address the main open point from my earlier validation: the candidate WGPU result on RTX 4060/Vulkan (0.0574 m RMSE) is within 0.0022 m of CUDA (0.0552 m), while the original WGPU path retains the large range error. It is also reassuring that the Apple Metal result reproduced on Vulkan within a few percent. I agree with your interpretation of the 511 -> 512 case. Since the observed differences are below one range bin and the mapping reduces to a plain copy when the padding ratio is 1.0, an additional threshold or no-op branch does not appear necessary. I will keep the correction unconditional. As a separate follow-up, we also evaluated an exact-length Bluestein WGPU FFT prototype. This is not the implementation in PR #44 and is not an end-to-end DAVE/Gazebo/ROS 2 sonar result, but it provides evidence for a possible future arbitrary-length FFT path:
These standalone results support the numerical feasibility of an exact-length alternative, but they do not replace the end-to-end validation of the current linear-interpolation correction. For this PR, your CUDA/Vulkan reproduction and sweep provide the directly relevant evidence. Thank you as well for being open to the paper discussion. I would be happy to discuss the technical scope, remaining experiments, and contributions in a separate thread or call. |
|
Hi @naitikpahwa18, I have now synchronized the latest
I also added the macOS dynamic-library search paths required by the sonar and sonar-system plugins. During runtime validation, Validation completed on Apple M2 / arm64 with ROS 2 Lyrical and Gazebo Jetty:
The synchronization is in I updated only the PR branch; PR #44 remains open and has not been merged into |
Signed-off-by: Yeseol Gwon <172019512+yeseorizi@users.noreply.github.com>
Publish macOS loader paths for both sonar libraries and replace the two byte-copy cv_bridge conversions with a local ROS image copy. This avoids unnecessary OpenCV ABI coupling while preserving BGR8 and RGB8 message output.

Signed-off-by: Yeseol Gwon <172019512+yeseorizi@users.noreply.github.com>
for more information, see https://pre-commit.ci

a83a91a to
720eb3d
Compare
for more information, see https://pre-commit.ci


Summary
This PR removes the CUDA dependency from the multibeam sonar implementation and introduces a modular compute backend architecture. A new WGPU-based compute backend is added along with a CPU reference backend used as a fallback when GPU execution is unavailable.
The sonar sensor was refactored to use this backend interface instead of calling CUDA kernels directly. The WGPU implementation runs the sonar compute stages on the GPU using WGSL shaders, while the CPU implementation preserves the existing physics model for deterministic results.
The build system was updated to remove CUDA requirements and integrate a Rust-based WGPU vendor package. Runtime backend selection is also supported.
Validation
The WGPU backend has been tested on Vulkan; support for Metal and DirectX backends is expected via WGPU but remains untested.